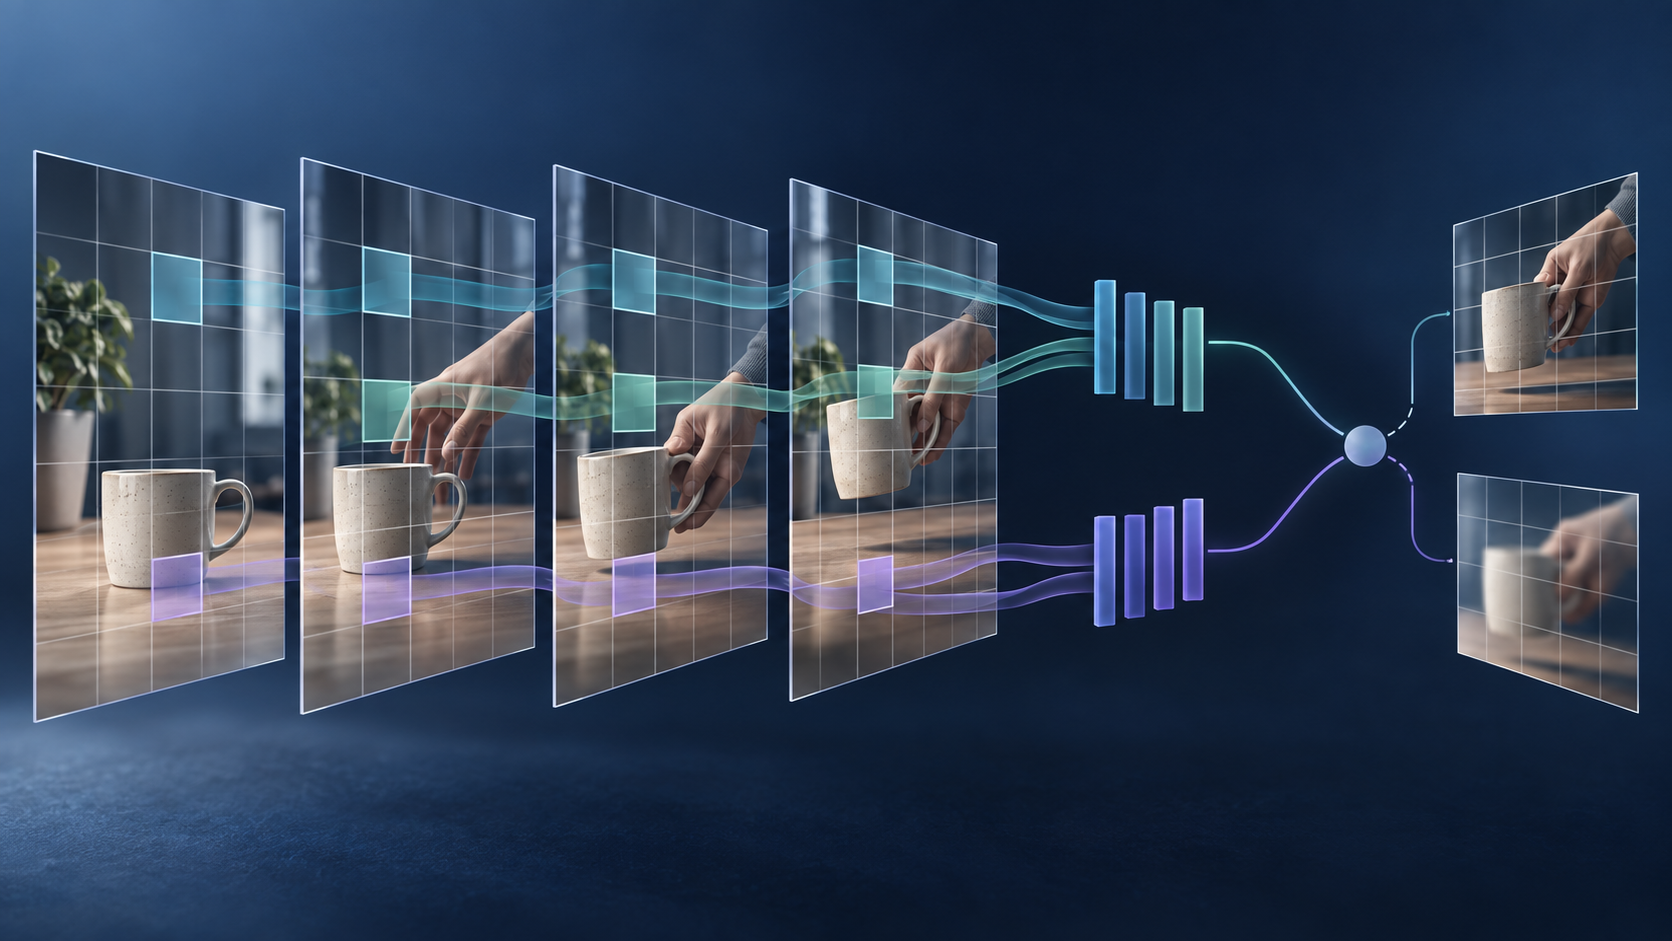
V-JEPA: Learning Video Representations by Feature Prediction
JEPA
Computer Vision
Deep Learning
Video
Python
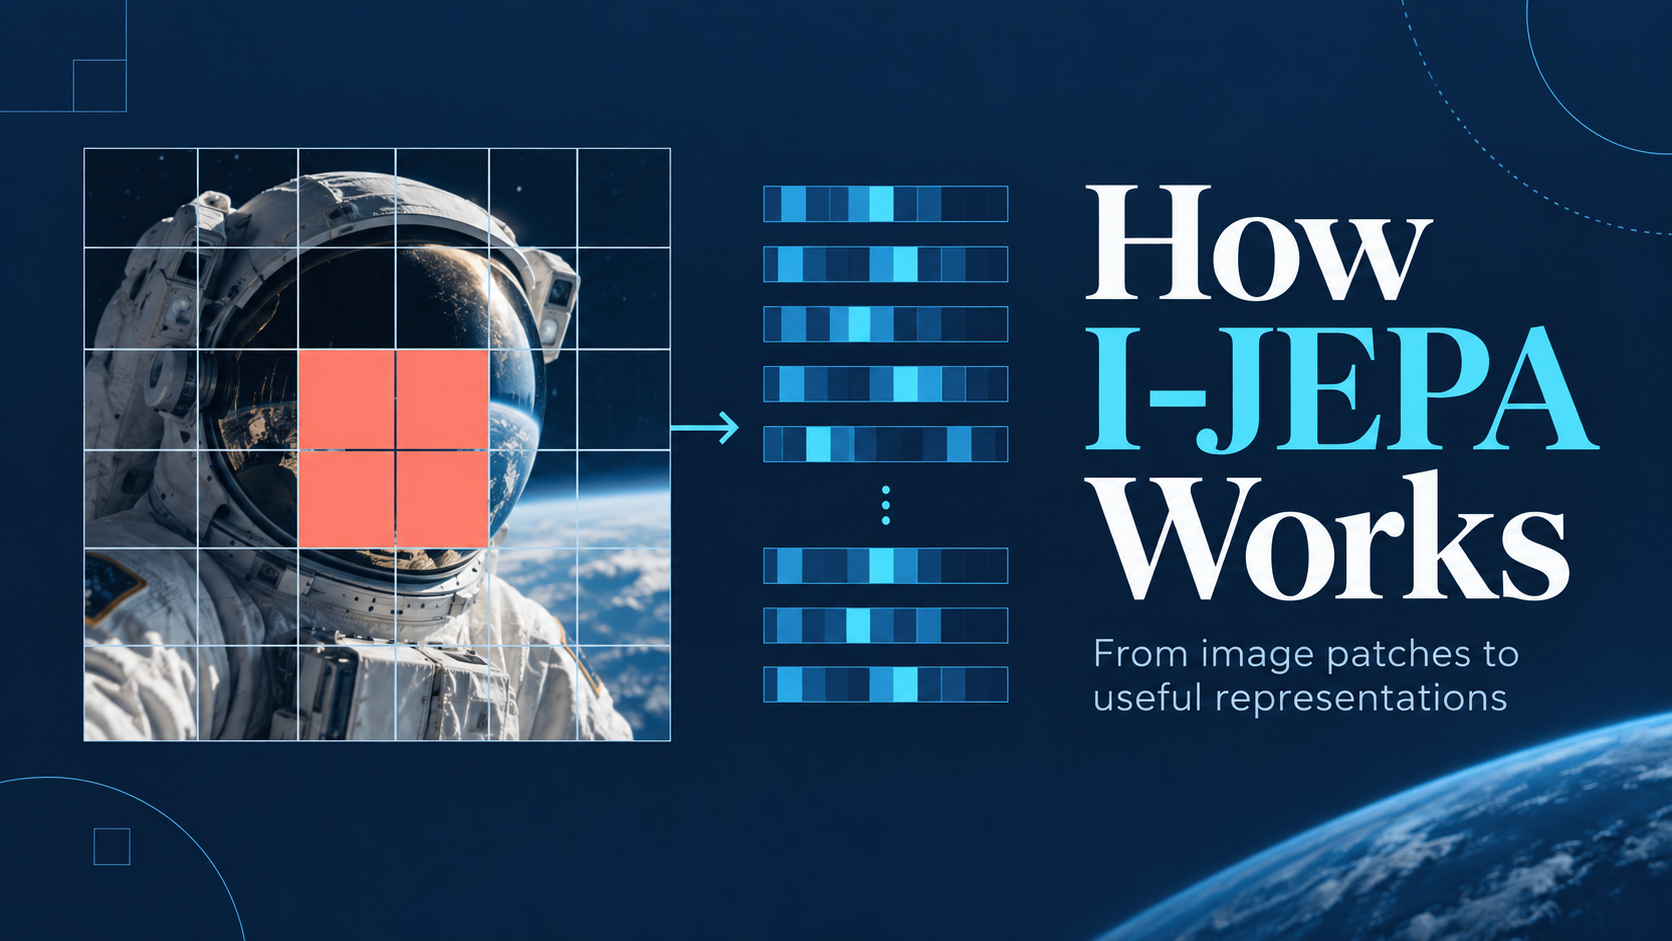
Follow V-JEPA ViT-L/16 from video tubelets and feature prediction to pretrained encoder features, temporal tests and a small action-classification experiment.
25 Sep 2026